Our Technology
The infrastructure behind
financial institutions’ ESG data sourcing.
Our data pipeline sources, extracts and structures ESG data from public company information. Our AI does the repetitive work, and human experts review every datapoint before delivery.
01 · Sources
Everything a company officially publishes.
02 · Extraction & Quality
AI structures the data, analysts sign off, monitoring keeps it current.
03 · Platform
Data is available in our platform, as file exports, or via API.
FINDING COMPANY INFORMATION
Everything a company officially publishes.
EXTRACTING, STRUCTURING & VERIFYING DATA
AI structures the data. ESG data experts sign it off. Agent monitoring keeps data current.
PLATFORM DELIVERY
Delivered via Cleartraced’s platform, offering file export or API integration, whatever fits your infrastructure.
THE CLEARTRACED DATA PIPELINE
From scattered company information to structured, auditable ESG data.
Adding a company
We only need three inputs to run our process: the company’s country, the reporting year, and its name or identifier. New companies can be requested in whichever way is easiest for you: via email, a form within our data platform, an API request, or a file over SFTP, always handled with total privacy and confidentiality.
Request · 3 inputs
Name or identifier
Country
Reporting year
Finding public information
Our system scans each company’s official webpages, downloads its annual, sustainability and regulatory reports, and combs the full site for further ESG disclosures such as human-rights policies and codes of conduct, tying every document to the right entity.
SOURCING
Process reports
Our system reads PDFs, scans complex tables and charts and converts them into structured, machine-readable text, handling complex layouts and any language.
Structured JSON
{
  "text":  "…",
  "table": […],
  "chart": {…},
  "image": "…"
}
Extract & structure
Structured AI prompts extract each datapoint in context, with high precision, and harmonise it to standard units.
As reported (PDF)
Normalised
Units converted (kg → tCO₂e) and currency harmonised (SEK → EUR)
Normalise & standardise
Every value is mapped into common taxonomies and regulatory frameworks before storage, enabling consistent cross-company comparison.
Verification
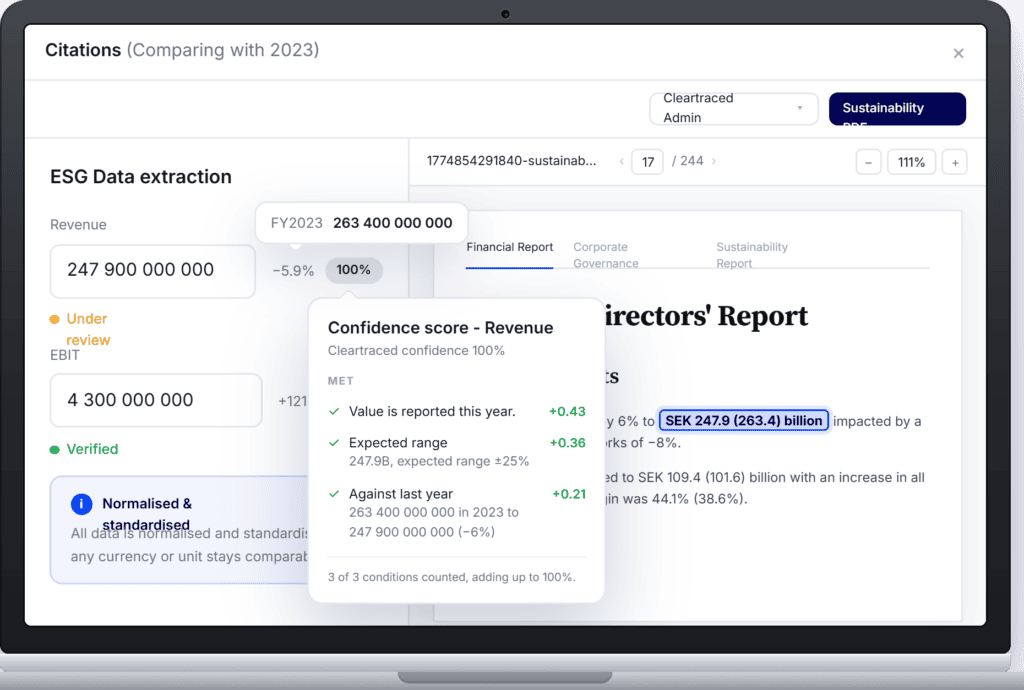
A rule-based system scores every datapoint across five layers. Anything below the confidence threshold is routed to an ESG analyst; nothing is guessed or dropped.
Quality score
Store & deliver
Validated data is stored securely and delivered in real time via platform, API or file, each datapoint linked to its source and re-verified against the original PDF.
THE TECHNOLOGY ADVANTAGE
What our technology enables that humans and legacy providers simply cannot.
Human teams can only cover so many names. Our pipeline has no ceiling: any company that discloses, whatever its size or market.
No fixed list of metrics. If a company discloses it, we extract and structure it, down to the datapoints your analysis needs.
AI reads disclosures natively in any language. No translation queue, no blind spots for non-English markets.
We track each company’s release dates and monitor for new disclosures. The moment data is published, the pipeline picks it up.
FAQ
Common questions about our technology
How does Cleartraced find the public information and PDFs? +
What AI models power the extraction? +
How is data accuracy verified before delivery? +
Can the pipeline handle non-English reports? +
How quickly is data updated after a company publishes a new report? +
Built with cutting-edge technology



Want to see it in action?
Book a demo and we’ll run a live extraction on any company worldwide.